# Slash, manage, and optimize AI cost structures
Reduce agentic LLM token consumption and drive greater LLM cost efficiency with the Kong Konnect API platform
## LLM innovation without AI cost optimization is unsustainable
LLM usage isn’t cheap. Depending on the scale of your AI programs — and especially if those programs leverage Agents — overall compute and LLM token consumption can mean a major cost burden to your business.
But it doesn’t have to.

## Implement multi-layer LLM controls for end-to-end AI cost management and budget optimization
Enforce organization-wide token-based rate limiting and throttling to ensure that you stay within agreed-upon token consumption.
Adopt multiple models, with the ability to dynamically route to the optimal model by cost, prompt semantics, latency, and more.
Enforce consumption limits and cost controls across the entire AI stack — from the MCP server, to the LLM, to the various APIs and tools being called — all in one platform.
## Because AI hyper-innovation should mean hyper-growth and hyper-efficiency

## Multi-model semantic intelligence
Enforce semantic caching to have the gateway provide direct responses to similar prompts. [Enforce semantic routing](/resources/demos/kong-konnect/run-and-secure-llm-traffic)Enforce semantic routing to ensure that only the best model is chosen for the job. *Both* reduce token consumption and cost.
## MCP traffic control
MCP is great, but it results in much more LLM and consumption. Use the Kong AI Gateway to control MCP traffic and keep costs under control as you still drive innovation.

## Automate cost control
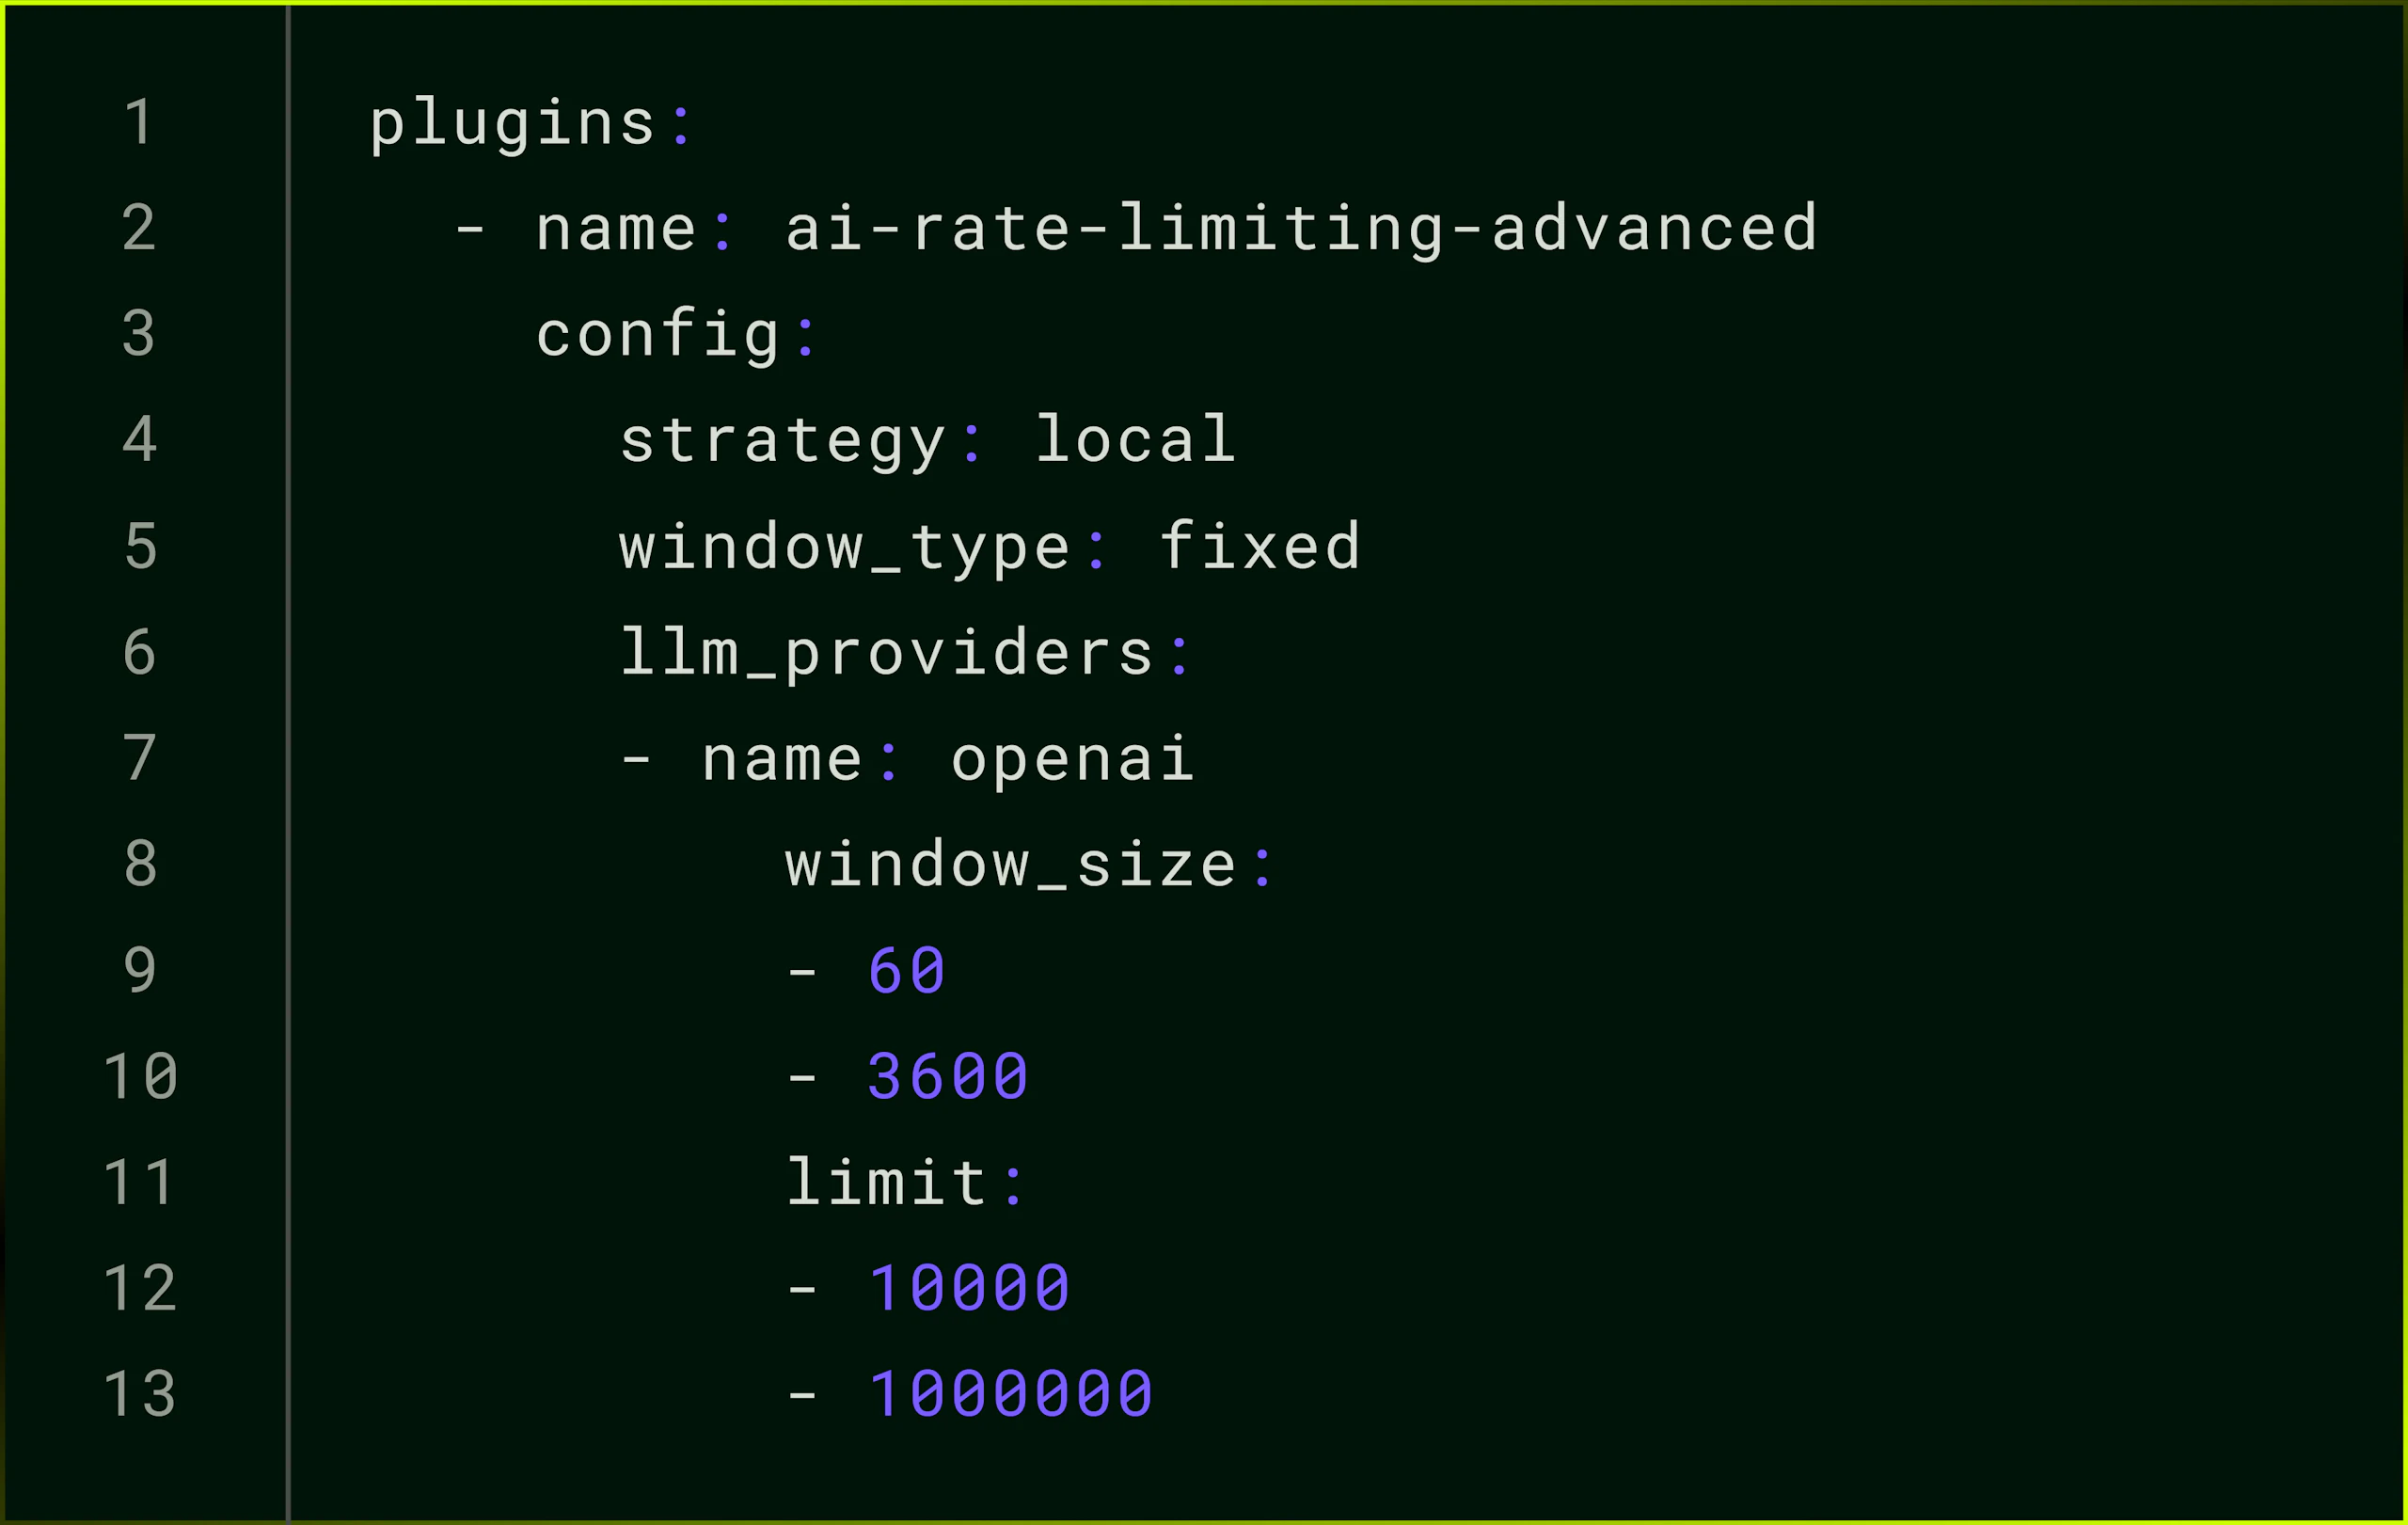
Enforce global and/or LLM-specific token-based rate limiting and throttling to control LLM token consumption and spend across your organization. Automate these policies as guardrails to ensure that no AI project goes rogue.
## Reduce overall dev time and engineering spend
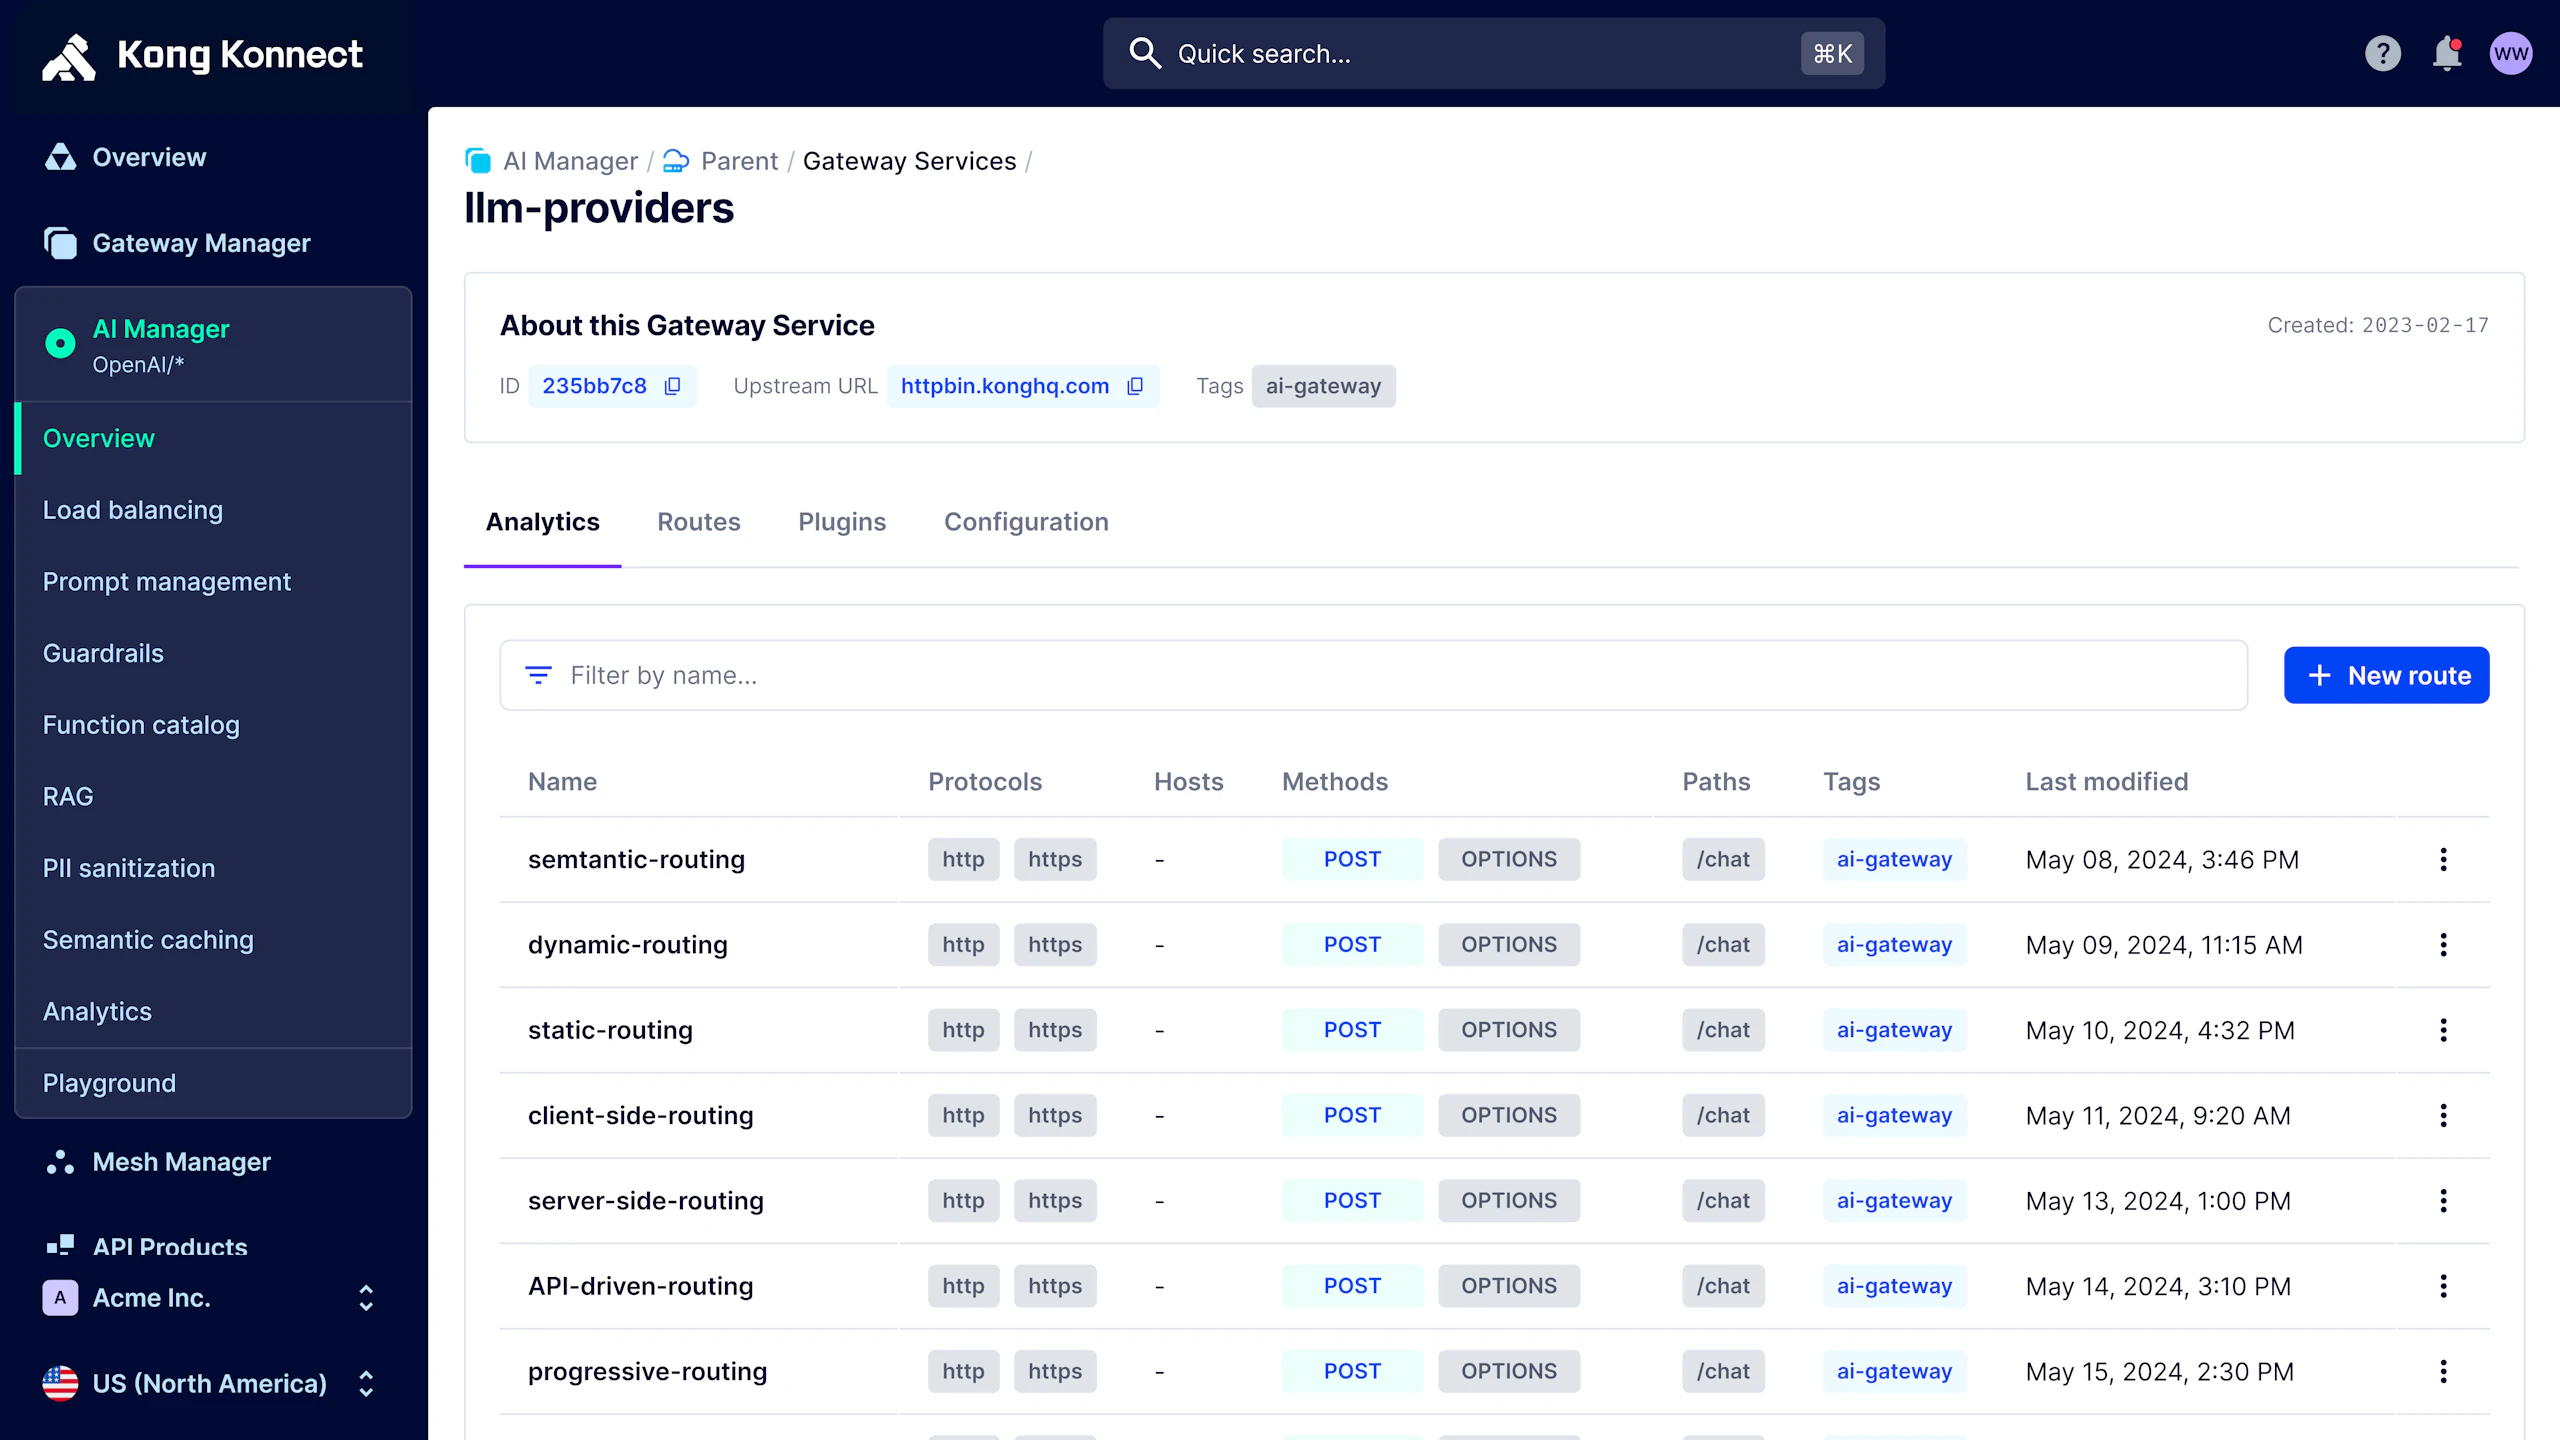
Replace time-consuming, one-off application-to-LLM integrations with a single, universal API layer that any application can consume.
## Observe all AI consumption
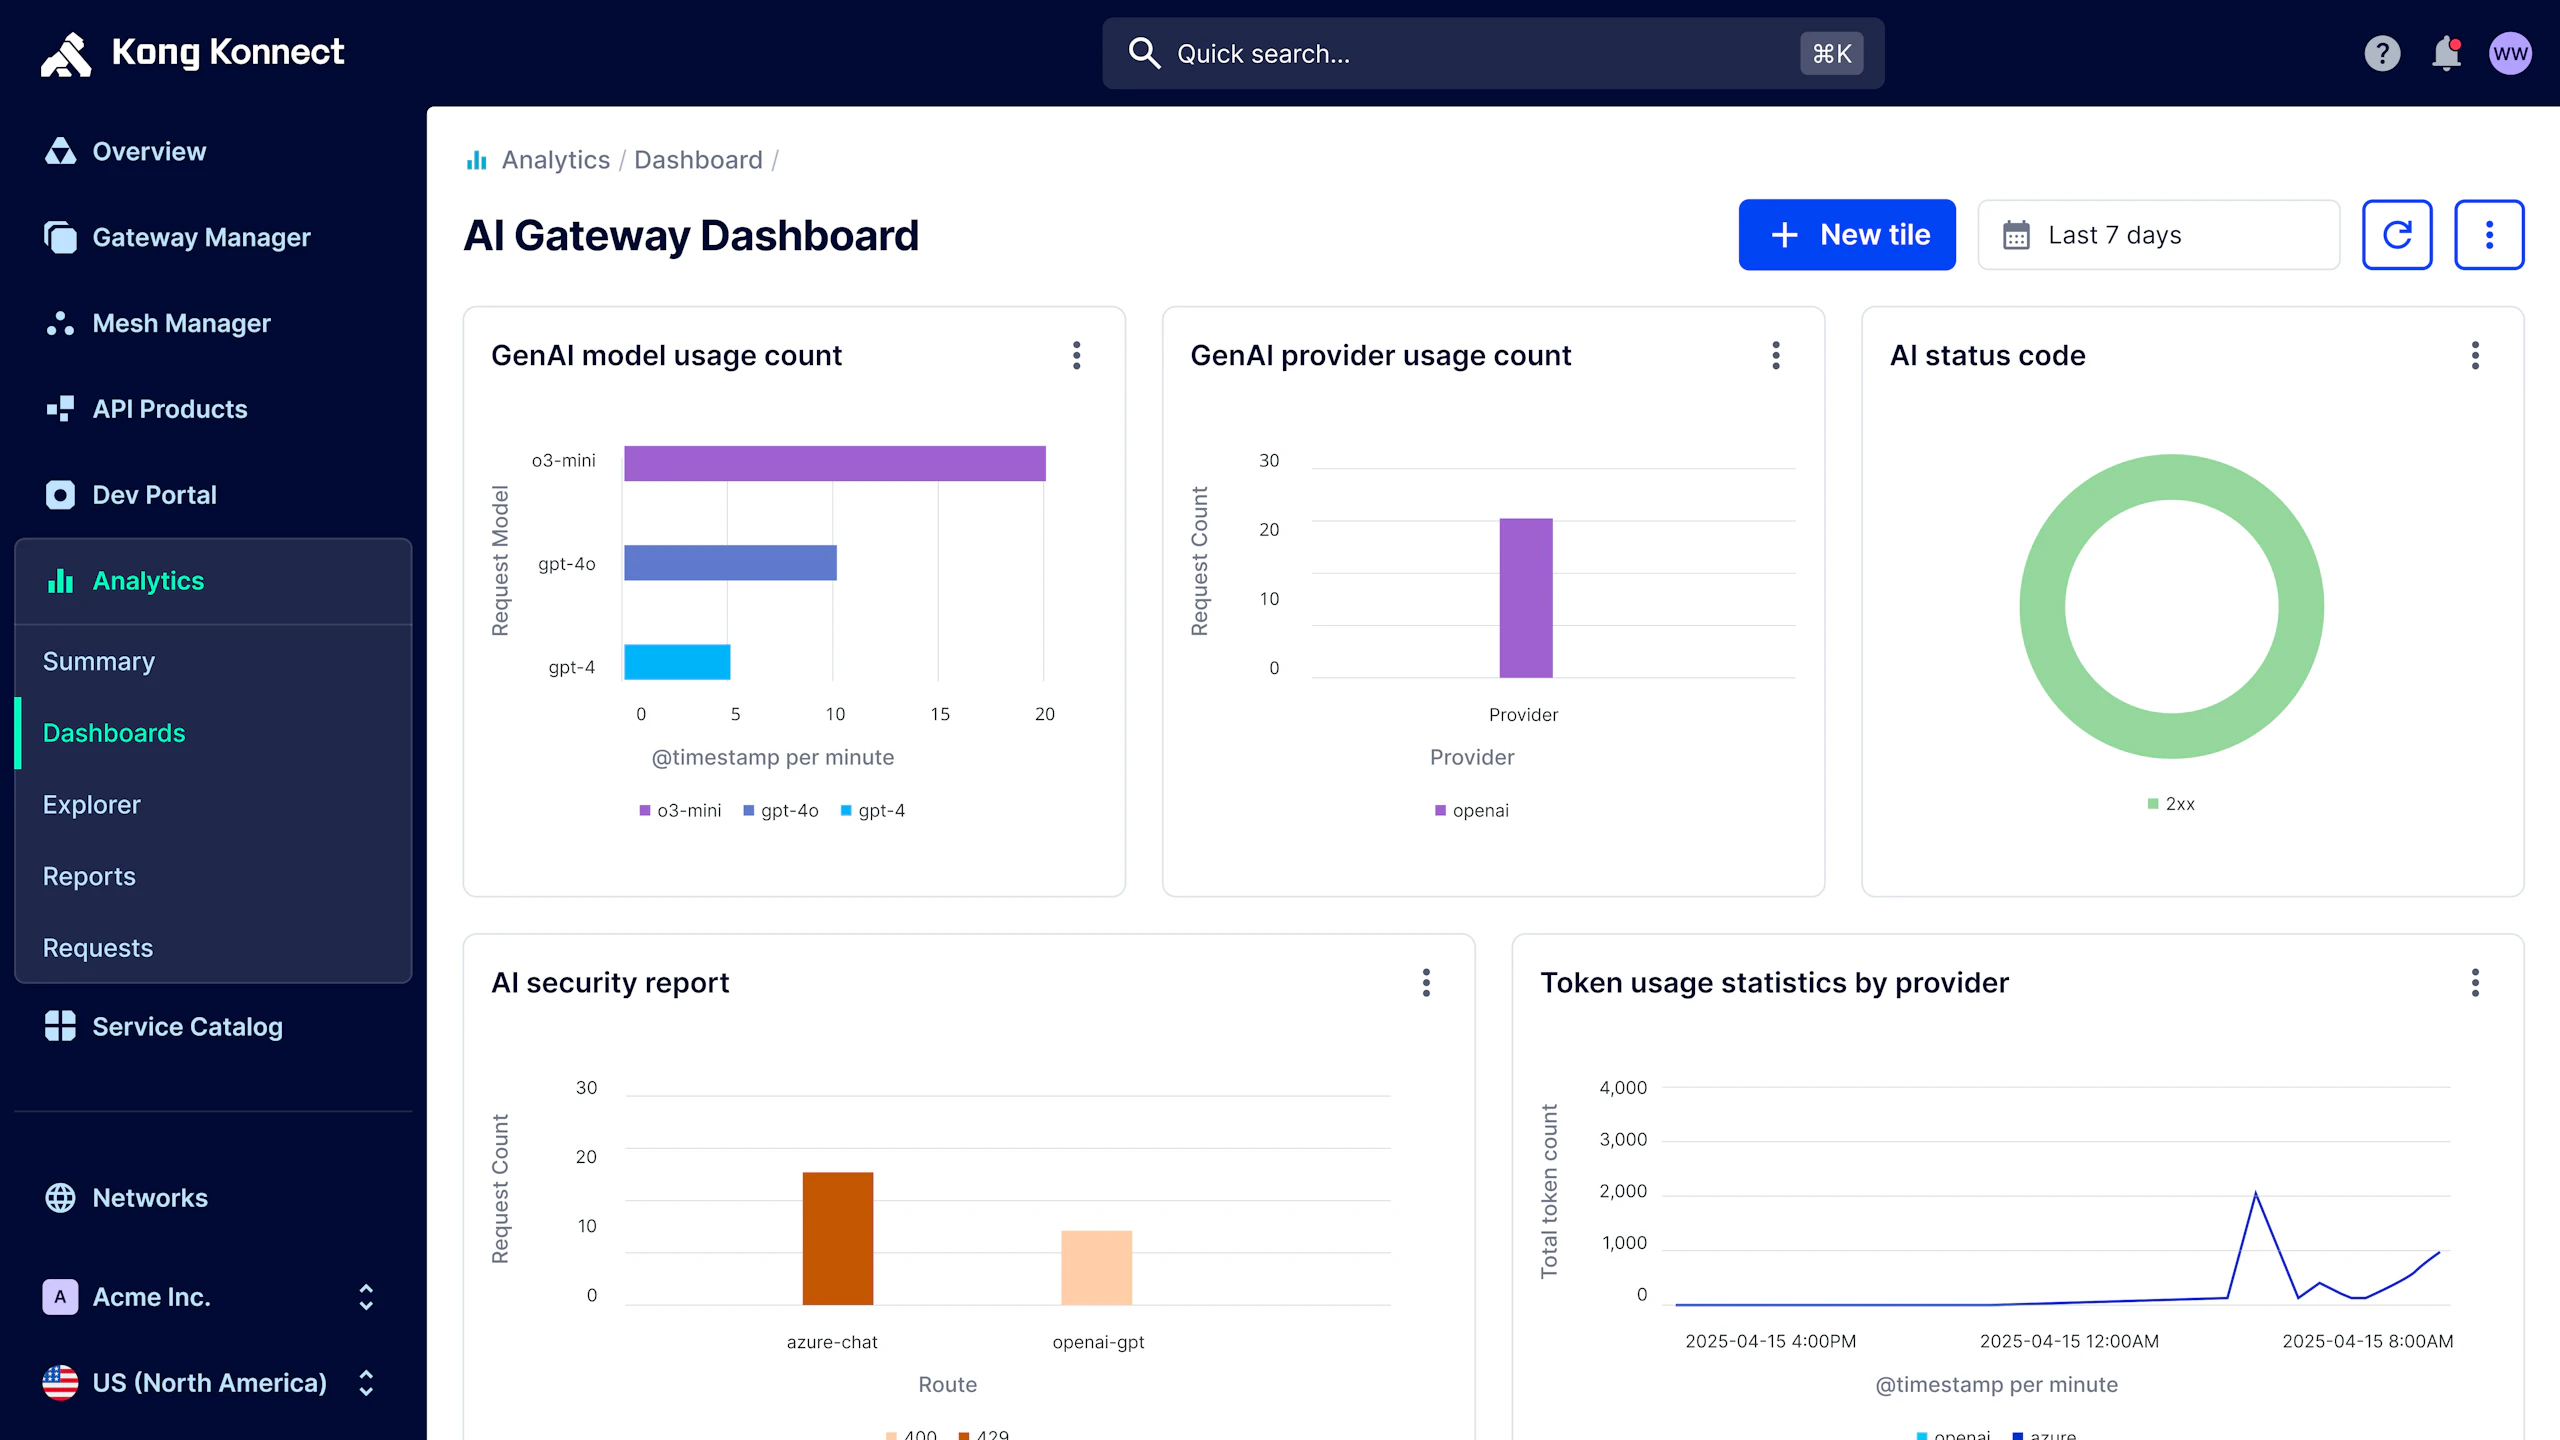
Stand up analytics and observability dashboards that give platform and executive teams rich insight into MCP, LLM, token, and API consumption.

## Gartner® names Kong a Leader for 7th year.
Once again, furthest right for Completeness of Vision.
[Learn More](/resources/reports/gartner-magic-quadrant-full-lifecycle-api-management)Learn More
## Related Resources
### Streamline AI Usage with Token Rate-Limiting & Tiered Access
Learn how to use Konnect and the AI Gateway to streamline LLM token consumption and control AI costs.